Technical Solution 17: How ModSecurity and Hosting Security Can Block AI Crawler Access
A Real-World AI Retrieval Case Study When Security Rules Blocked Access
Every day, we solve problems for eCommerce website owners. We had a think about how we might use this activity to help others, and came up with this idea: Every week or three, we'll take the trickiest problem and publish our solution.
Important! - Some of these solutions involve adding code to your website (WordPress and Woocommerce mostly), so please ALWAYS be careful. We are not in any way responsible, directly or indirectly for any impact or consequences our code or advice has on your website, nor are we liable for any damage arising from such use.
Always back up your website before changing or adding code and/or editing the database, This is critically important!!!
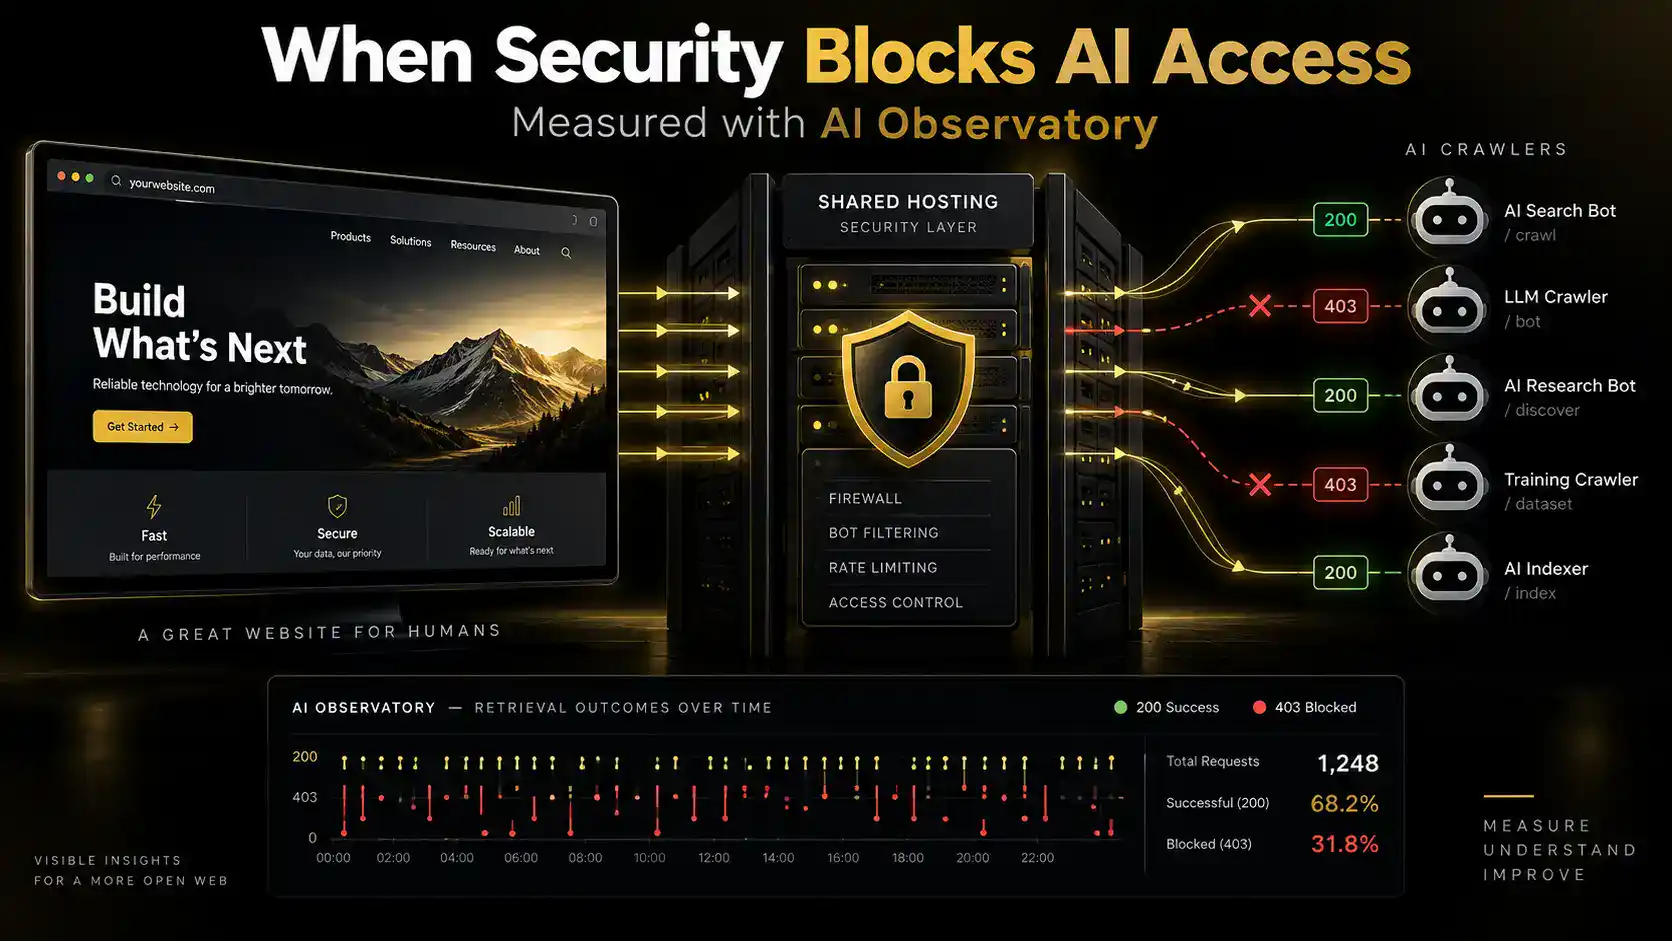
ModSecurity and other hosting security layers can affect AI crawler access even when a website appears healthy to human visitors. AI Observatory measures the actual retrieval outcomes.
The Website Worked Normally — But AI Crawlers Were Getting 403 Errors
For this case study, I’ll call the affected shared-hosting site “A Website”. To its owner, and to anyone opening it in a browser, everything looked normal.
AI Observatory showed otherwise. Recognised AI crawlers were sometimes being refused access.
This was not a theoretical problem. We had actual autonomous crawler requests in the hosting logs and actual HTTP responses from the server. Some succeeded normally. Others came back 403 Forbidden.
A website being online does not prove that AI crawlers can reliably retrieve it.
At one point, measured retrieval of the website’s public business information had fallen to about 46%. After changes were made in the hosting and security environment, it recovered through 66.7%, 77.2%, 85%, 86.4% and eventually 93.3%.
These were rolling production measurements, not a laboratory test. But the direction was very clear. Something in the hosting environment was affecting crawler retrieval while the website itself continued to work normally for people.
Then the problem changed shape.
Verified OpenAI crawler traffic began showing intermittent 403 responses. GPTBot and OAI-SearchBot could get through at one time and be refused at another, while other recognised crawlers continued to retrieve the website successfully.
The Website Looked Healthy
Human browsing continued to work normally. An owner checking the site in a browser would have had no obvious reason to think there was an access problem.
The Failures Were Measurable
AI Observatory was recording the real crawler requests and the HTTP responses they received. We were not inferring access from robots.txt, crawler permissions or the fact that the website happened to open in a browser.
Security Can Act Selectively
Shared-hosting security does not have to take a website offline to cause trouble. It can allow one request and refuse the next. ModSecurity, reputation systems, bot filtering, rate controls and other hosting-layer systems can all affect the result.
A 403 Does Not Identify the Culprit
A 403 tells you that the request was refused. It does not tell you who refused it. The decision could have come from ModSecurity, Imunify360, LiteSpeed, Wordfence or another part of the stack. We needed more evidence before blaming any one of them.
So the next question was no longer, “Is the website up?”
It plainly was.
The question was: which layer of the hosting stack was deciding whether legitimate AI crawlers were allowed through?
AI Observatory Exposed a Failure That Human Browsing Could Not See
The first number I cared about was not page speed, uptime or whether I could open the site in a browser. It was much simpler: when a recognised crawler asked for the website’s public business information, did it actually get it?
At one stage, A Website was recording only about 46% successful retrieval. That is not a small miss. More than half of the qualifying retrieval attempts we were measuring were failing while the website itself carried on looking perfectly normal to people.
Rolling AI Observatory measurements taken during the hosting investigation. These are snapshots of the website at different points in the recovery, not laboratory test results.
Security Changes Coincided With a Major Recovery
During the investigation, the host made a ModSecurity adjustment for the website. Retrieval improved markedly afterwards. Later, the provider also acknowledged and corrected a separate CloudLinux problem, and the measured recovery continued.
I am being careful with the wording here. Those measurements show that the hosting and security environment mattered. They do not prove that every failed request came from one ModSecurity rule, or even from one product.
Then OpenAI Crawlers Began Showing Intermittent 403 Responses
Later we found something more specific. Verified OpenAI crawler requests were reaching the hosting environment, but some of them were coming back HTTP 403 Forbidden.
More importantly, the block was not consistent. The same crawler families could get through at one time and be refused at another.
OAI-SearchBot requested /robots.txt from one verified OpenAI source address and received 403 — 787 bytes.
One second later, GPTBot requested / from a different verified OpenAI source address and also received 403 — 787 bytes.
OAI-SearchBot requested /robots.txt and received 403 — 5015 bytes.
At the same second, GPTBot requested / from another verified OpenAI address and received 403 — 5015 bytes.
That was interesting. Two different OpenAI crawler systems, coming from different source addresses and asking for different resources, were refused at almost the same moment. In each pair the 403 response sizes matched.
That does not tell us which security product did it. But it is very hard to explain as a missing page or a simple crawler mistake.
The Block Was Not Permanent
At 22:01 UTC it changed again. OAI-SearchBot retrieved /robots.txt successfully with a 200 response. At the same time, GPTBot requested the website root and received a normal 301 redirect.
We also had earlier successful GPTBot retrievals. So this was plainly not a permanent ban on GPTBot or OAI-SearchBot. Whatever was happening, it was intermittent.
AI Observatory changed the question. Not “Is the website online?” We already knew that. The useful question was: “When a legitimate AI crawler asks for the public information, what does the hosting stack actually give it?”
A 403 Can Be Generated Before WordPress Serves the Page
On shared hosting, an AI crawler does not simply talk straight to WordPress. Its request can pass through several server and security layers first. Any one of them can say no before WordPress sees a thing.
That is why an HTTP 403 Forbidden is useful evidence, but only up to a point. It tells us the request was refused. It does not identify the system that refused it.
ModSecurity may be responsible. So might provider filtering, Imunify360, LiteSpeed or Apache controls, rate limits, reputation systems or, further down the chain, something inside WordPress such as Wordfence.
“403 Forbidden” tells us what happened to the request. It does not tell us which security layer did it.
Simplified request path for explanation. The actual order and products vary between hosting environments.
ModSecurity
ModSecurity is a web application firewall engine. It checks HTTP requests against security rules and can reject one before WordPress handles it. The crawler gets a 403 while everyone else may carry on using the website normally.
Imunify360 and Provider Security
A shared host may also run reputation, malware, firewall and behavioural controls outside WordPress. The awkward part for the website owner is that the decision — and sometimes even the useful log — may exist only on the provider's side.
LiteSpeed or Apache Controls
The web server itself can enforce access rules, throttling, connection limits and other restrictions. If it rejects the request there, PHP may never run and WordPress may know nothing about it.
WordPress and Wordfence
WordPress security can certainly block automated traffic, but it sits later in the chain. If something upstream has already returned the 403, there may be nothing for WordPress or Wordfence to record.
That became important with A Website. We could see the OpenAI requests in the raw hosting access log. We could also see the server returning 403s. But the source addresses involved in those failures were not showing up in the Wordfence evidence we examined.
We checked Wordfence's own logs and database records, including its hit history, blocked-IP records and active block table. The OpenAI addresses from the paired 403 events were not there.
The account-visible WordPress and PHP error logs were silent as well. At the same time, the shared-hosting account did not give us access to the underlying ModSecurity or Imunify security-event logs.
At that point there was not much value in staring harder at WordPress. The sensible place to look next was upstream.
The evidence pointed away from the application layer and toward a hosting or server-security decision occurring before WordPress. It still did not tell us which product or rule was responsible.
The Same Legitimate AI Crawlers Were Allowed, Blocked and Allowed Again
The raw hosting access log was where this became really useful. GPTBot and OAI-SearchBot were not simply disappearing somewhere on the Internet. Their requests were reaching the hosting environment, being logged, and getting different answers at different times.
We also checked that these really were OpenAI crawlers. The source addresses were corroborated against published provider network information. I was not prepared to trust a user-agent string on its own.
The number after each 403 is the response size recorded by the server. Normally that would be a fairly unexciting detail. Here it caught my attention.
At 17:29, two different OpenAI source addresses asking for two different resources both received the same 787-byte 403 response. At 18:21 another pair did the same thing, this time at roughly 5015 bytes.
Coincidence is possible. But once two separate crawlers start failing together and returning matching responses, it is worth following.
Verified OpenAI Traffic
We did not call these OpenAI requests just because they said GPTBot or OAI-SearchBot. The source addresses were checked against published provider network information before the traffic was admitted into the Observatory evidence.
The Block Was Intermittent
The same crawler families got successful responses, 403 failures and ordinary redirects at different times. That does not look like a simple permanent robots.txt or user-agent block.
The Failures Were Synchronized
Two separate OpenAI crawler requests failed within one second at 17:29. Another two failed at exactly the same second at 18:21. Different source addresses were being affected together.
Two Distinct 403 Sizes Appeared
The failed responses fell into two obvious size groups: 787 bytes and roughly 5 KB. That may indicate different denial templates or handling paths. It is a clue, not proof of which security product produced them.
This was not an AI crawler that simply “could not reach the website”. The requests reached the hosting environment. Sometimes they were allowed. Sometimes they were refused.
That difference matters. A missing page normally stays missing. A fixed configuration error is usually repeatable. A permanent block normally keeps blocking.
That was not what we had.
We had state-dependent access: verified OpenAI traffic succeeded, failed, and then succeeded again. Something in the hosting or security stack was making decisions from one request to another.
Which brought us to the next question: who, exactly, was producing those 403s?
WordPress Was Not Showing the Blocks — So We Kept Moving Up the Stack
Once the raw access log had confirmed real 403 responses, the job was to find out where they came from. So we started with the security system we could actually inspect ourselves: Wordfence.
We checked the affected OpenAI source addresses against Wordfence's available logs and database records: event files, hit history, blocked-IP records and the active block table.
The failed OpenAI addresses were not there. We then checked the WordPress and PHP error logs available through the hosting account, looking for the same addresses, 403 events, access-denied messages and anything referring to ModSecurity.
Nothing useful turned up there either.
A missing application log entry does not mean the block did not happen. It can mean the request was stopped before the application ever saw it.
What We Knew
- The OpenAI requests reached the shared-hosting environment.
- The server logged genuine HTTP 403 responses.
- The source addresses had been corroborated as OpenAI infrastructure.
- The failures were intermittent, not permanent.
- We found no matching Wordfence block records for the affected addresses.
- The account-visible PHP and WordPress logs showed no corresponding denial event.
What We Still Did Not Know
- A 403 on its own did not prove that ModSecurity generated it.
- The customer account did not expose the provider's ModSecurity audit log.
- The relevant Imunify360 security-event records were not available to us.
- We could not inspect every LiteSpeed or provider-level security decision.
- The two 403 response sizes were useful clues, but did not identify the mechanism.
- The final answer required logs controlled by the hosting provider.
This is one of the awkward realities of shared hosting. You own the website, but you do not necessarily control — or even get to see — every system that handles an incoming request before it reaches your code.
Application Evidence
WordPress, Wordfence and PHP were the parts we could inspect directly. Nothing we found there showed Wordfence blocking the OpenAI addresses involved in these 403 events.
Web-Server Evidence
The raw hosting access log was different. It showed the requests and the HTTP answers returned to them. The 403s were real. They were not an AI Observatory interpretation and they were not a browser artefact.
Provider Security Evidence
The remaining useful evidence sat higher up the stack. ModSecurity, Imunify360 and other provider-managed systems may have logs that only the host can see. At that point we needed the provider.
So we gave the host something much more useful than “AI bots seem to be blocked”.
They were given the exact UTC times, source IP addresses, crawler identities, requested paths, status codes and response sizes. In particular we pointed them to the paired failures at 17:29 UTC and 18:21 UTC on 19 September 2026.
The question was equally specific: which server or security layer generated those exact 403s, and what rule or decision produced them?
By this point the evidence pointed upstream of WordPress and toward the hosting or server-security layer. What it did not yet tell us was whether ModSecurity itself caused the later OpenAI failures. That needed the provider's logs.
What Should You Do When an AI Crawler Receives a 403?
My first reaction would not be to switch off ModSecurity, disable Wordfence or ask the host to whitelist half the Internet. First find out what actually happened.
Was the crawler genuine? What did it request? What response did it get? And, most importantly, which layer of the system made the decision?
-
Confirm That the Resource Really Is Public
Start with the obvious. Open the exact URL in a private browser session and make sure it is genuinely public, current and does not require a login, cookie, session or some other interaction. That proves the page is available to a normal visitor. It does not prove a crawler can retrieve it.
-
Measure the Crawler Request, Not the Browser
A browser visit and a crawler request are two different tests. Look at the actual server or edge evidence: which crawler asked, which path it requested, which method it used and what HTTP response came back. This is exactly why we built AI Observatory.
-
Record Exact Times and HTTP Outcomes
Keep the UTC timestamp, crawler identity, source address, requested resource, status code and, if you have it, the response size. “GPTBot seems to be blocked” is not terribly useful. “This IP requested this URL at 18:21:37 UTC and received a 403” is something a hosting engineer can actually investigate.
-
Verify the Crawler Identity
Do not trust the name in the user-agent on its own. Check the source against the provider's published network information or another suitable verification method. Any script can call itself GPTBot or Googlebot. That is not a reason to weaken security for it.
-
Work Through the Security Layers
Start with what you can see. Check WordPress security plugins, application and PHP logs, the web-server access log and any ModSecurity or hosting-security information available to you. If the server saw the request but WordPress did not, that is a useful clue: start looking upstream.
-
Do Not Assume Every 403 Is ModSecurity
ModSecurity can certainly return a 403. So can Imunify360, LiteSpeed, Apache controls, reputation filtering, bot protection, connection limits and other provider-managed systems. Do not name the culprit until the evidence does.
-
Escalate With Evidence, Not a General Complaint
If the useful logs belong to the hosting provider, give support the exact time, IP address, user-agent, requested URL, response code and anything else that identifies the event. Then ask a precise question: which layer generated this response, and which rule or decision caused it?
-
Make the Narrowest Safe Correction
If a legitimate crawler is being incorrectly blocked, fix the particular conflict. Change the rule or make a tightly scoped exception. Do not switch off the whole WAF, allow an entire cloud network or broadly whitelist automated traffic just to make one crawler statistic look better.
-
Measure Again After the Change
This last step matters. Changing a setting does not prove that you fixed anything. Measure the crawler again and make sure legitimate retrieval now works without opening the door to unrelated automated traffic.
In Practice, You Usually End Up in One of Three Places
The Application Blocked It
WordPress or an application-level security product recorded the refusal. Good. You have something you can inspect, and usually a specific rule or event to work from.
The Hosting Layer Blocked It
The server received the request but something stopped it before WordPress handled it. ModSecurity, Imunify360, web-server controls or another provider-managed system may be responsible. Now you need the server-side evidence.
The Evidence Is Incomplete
You can see the 403 but not the log that explains it. That is the point to escalate to the hosting provider. It is not the point to start randomly turning security controls off.
Do not switch off ModSecurity just because an AI crawler received a 403. First establish that ModSecurity actually produced it. Then find the rule that needs attention.
The aim is not to build a website that accepts every bot that knocks on the door. It is to keep the normal protections in place while making sure legitimate autonomous crawlers can retrieve the public business information you actually want them to see.
And that comes back to measurement. robots.txt tells a crawler what you intend to allow. Security configuration tells the server what you intend to permit. The retrieval evidence tells you what really happened.
AI Crawler Access Is a Shared Responsibility
The website owner can make the information public and allow legitimate crawlers. What the owner cannot necessarily do on shared hosting is control every security decision made before the request reaches WordPress.
The hosting provider has a part to play as well. But equally, a host should not be expected to trust a request simply because it says it is an AI crawler. The crawler needs an identity that can actually be checked.
In practice, reliable AI crawler access needs three things to line up: the website must be configured sensibly, the hosting stack must not incorrectly reject legitimate traffic, and the crawler must be verifiable.
The Website Owner
- Keep the important public business information genuinely public.
- Keep robots.txt and crawler permissions sensible and consistent.
- Do not weaken security just to improve a crawler success figure.
- Measure real crawler retrieval instead of relying on browser tests.
- Keep exact timestamps and technical evidence when something fails.
- Escalate unexplained hosting failures with evidence, not guesswork.
The Hosting Provider
- Run security without unnecessarily blocking legitimate public retrieval.
- Check ModSecurity, Imunify360, LiteSpeed and other server-level systems when the evidence points there.
- Identify the actual rule or mechanism behind a 403 where possible.
- Fix the specific problem rather than weakening wider protection.
- Provide useful technical evidence when the relevant logs are not visible to the customer.
- Recognise that crawler access can fail while the website still looks perfectly normal to people.
The AI Platform
- Use stable and clearly documented crawler identities.
- Publish enough network information for those identities to be checked independently.
- Distinguish autonomous crawling, Search and user-directed retrieval where those functions differ.
- Do not require website owners to trust entire cloud networks just to admit one crawler.
- Use normal standards-based retrieval behaviour wherever practical.
- Make legitimate crawler traffic distinguishable from somebody merely pretending to be it.
What Happened With A Website?
A Website was already allowing legitimate crawlers, and AI Observatory could show successful retrieval by recognised autonomous systems. Human visitors had no problem with the site either.
Yet verified OpenAI crawler traffic was still failing intermittently. Our application-level checks did not show Wordfence blocking those requests, while the logs needed to finish the diagnosis sat with the hosting provider.
So that is where the evidence went: exact times, source addresses, crawler identities, requested paths, response codes and response sizes. The provider's job was then to tell us which upstream security layer had actually generated the 403s.
What This Shared-Hosting Case Actually Proves
This is where it is easy to get carried away. We found a real retrieval problem and some very useful evidence. That does not mean every possible explanation suddenly becomes true.
So I have separated what we can actually say from what still needs the hosting provider's evidence.
What the Evidence Establishes
- A Website remained perfectly usable by people while measured crawler retrieval had fallen to about 46%.
- After hosting and security changes, retrieval recovered through 66.7%, 77.2%, 85%, 86.4% and 93.3%.
- A ModSecurity adjustment was part of the earlier remediation, and the hosting provider later acknowledged and corrected a separate CloudLinux problem.
- Verified GPTBot and OAI-SearchBot requests later reached the hosting environment and received genuine HTTP 403 Forbidden responses.
- Those OpenAI failures were intermittent. The same crawler families also received successful responses and normal redirects at other times.
- Separate OpenAI source addresses failed at almost the same moment, with paired 403 responses of matching sizes.
- We did not find those affected source addresses in the Wordfence evidence we examined, including hit records, blocked-IP records and the active block table.
- The WordPress and PHP logs available to us showed no corresponding denial event for those requests.
What the Evidence Does Not Establish
- It does not yet prove that ModSecurity generated the later OpenAI 403s.
- It does not prove that Imunify360, LiteSpeed, Apache or any other named provider-side component generated them either.
- It certainly does not mean every shared host treats AI crawlers this way.
- It does not mean GPTBot or OAI-SearchBot were permanently blocked from A Website. They plainly were not.
- It does not mean every 403 received by an AI crawler is a hosting-security problem.
- Nothing here suggests that the page content, schema or robots.txt caused these particular 403 responses.
- It gives us no reason to disable ModSecurity or broadly whitelist AI, cloud or automated traffic.
- And those two different 403 response sizes are clues. Useful clues, certainly. But they do not tell us which product generated them.
So What Can We Say?
Quite a lot, actually. Legitimate AI crawler retrieval can fail somewhere in the hosting and security stack while the website continues to look completely normal to human visitors.
In this case, the later OpenAI 403 pattern pointed us upstream of WordPress. To name the exact component responsible, though, we needed provider-side security logs that were not available in the shared-hosting account.
The lesson is not “turn off ModSecurity”. It is much simpler: measure the failure, find the layer, fix the specific problem, and measure again.
If AI Crawler Access Matters, Measure What the Server Actually Returns
Opening the site in a browser proves one thing: the browser got the page. It does not prove that GPTBot, OAI-SearchBot or any other legitimate machine system is getting the same result.
That was the whole point of this case. A Website looked healthy to people, yet AI Observatory measured retrieval down at about 46%. After changes in the hosting and security environment, that recovered as high as 93.3%. Later, we caught verified OpenAI crawlers receiving intermittent 403s.
ModSecurity was certainly relevant during the earlier remediation. That does not mean it automatically caused the later OpenAI failures. A 403 can be produced by several layers in a hosting stack.
So do not guess. Find the request, find the response, work out which layer made the decision, and then fix that specific problem.
The aim is not to trust every bot. It is to recognise legitimate traffic, measure what really happened, fix the actual conflict and check the result afterwards.
ModSecurity and AI Crawler Access: Common Questions
AI crawler failures can originate in several different parts of the hosting stack. These answers explain what a 403 means, where ModSecurity fits and why real retrieval evidence matters.
Can ModSecurity block AI crawlers such as GPTBot?
Yes. ModSecurity is capable of rejecting HTTP requests before they reach WordPress, including requests from legitimate AI crawlers. However, seeing a 403 Forbidden response does not by itself prove that ModSecurity caused it. Other hosting-security layers can return the same status.
Why can an AI crawler receive a 403 when my website works normally?
Human visitors and autonomous crawlers do not necessarily encounter identical security decisions. A hosting stack may evaluate source networks, request patterns, reputation signals, rate limits or crawler identity before allowing a request through. The website can therefore appear completely healthy in a browser while some machine requests are being refused.
Does a 403 error prove that ModSecurity blocked the request?
No. A 403 proves that the request was refused. On shared hosting, the response could potentially originate from ModSecurity, Imunify360, LiteSpeed or Apache controls, provider-level filtering, Wordfence or another security mechanism. The responsible layer should be identified from logs or provider-side evidence before changes are made.
Can Wordfence block GPTBot or OAI-SearchBot?
Yes, Wordfence can block automated traffic at the WordPress application layer. In the production case described on this page, however, the affected OpenAI source addresses were not found in the Wordfence logs, hit history, blocked-IP records or active block table that we examined. That evidence pushed the investigation further upstream.
Should I disable ModSecurity to improve AI crawler access?
Not simply because an AI crawler received a 403. ModSecurity provides an important security function. First determine whether ModSecurity actually generated the failed response and, if possible, identify the specific rule involved. A narrow correction is preferable to disabling an entire security layer.
How can I prove that an AI crawler is really reaching my website?
Use network, server or edge evidence showing the actual request. Record the crawler identity, source address, requested path, HTTP method, timestamp and response status. Where possible, corroborate the crawler identity against published provider network information rather than trusting the user-agent string alone.
Why is server-log evidence better than checking the website in a browser?
A browser test shows that one human-style request succeeded. It does not show what happened when GPTBot, OAI-SearchBot, Googlebot or another machine system requested the website. Server evidence records the actual machine request and the actual HTTP outcome returned to it.
What does AI Observatory measure?
AI Observatory records qualifying search and AI crawler retrieval activity against a production website and measures the HTTP outcomes of those requests. It distinguishes successful retrieval from failures and redirects using defined evidence rules rather than assuming that a crawler was successful merely because it appeared in a log.
Does AI Observatory prove that an AI system understood or used my content?
No. Retrieval evidence establishes that a qualifying machine system requested a resource and records what the website returned. It does not prove that the content was understood, indexed, cited, recommended, reused in an answer or used for model training.
What should I give my hosting provider when an AI crawler is being blocked?
Provide the exact UTC timestamp, source IP address, crawler user-agent, requested URL or path, HTTP response code and any useful response-size evidence. Ask the provider to identify which security layer generated the response and, where relevant, the specific rule or rule ID involved.
References and Supporting Material
Official technical documentation supports the discussion of web application firewalls, crawler verification and security-layer behaviour. The measured figures and HTTP events described in this case come from Sydney Business Web's AI Observatory, raw production access logs and the hosting investigation conducted on A Website.
Web Application and Hosting Security
- OWASP ModSecurity Open-source web application firewall engine used to inspect and act on HTTP traffic.
- OWASP Core Rule Set Documentation Rule-based web application firewall protection, anomaly detection, tuning and false-positive management.
- Wordfence Firewall Documentation Application-level WordPress firewall behaviour and blocking.
- Shared-Hosting Provider Security Logs ModSecurity, Imunify360, web-server and other provider-managed security logs may exist outside the customer's WordPress account and require hosting-provider investigation.
AI Crawler Identity and Verification
- OpenAI Crawlers Published information about GPTBot, OAI-SearchBot, ChatGPT-User and crawler identification.
- Cloudflare Verified Bots Verification principles for distinguishing recognised automated systems from self-declared bot traffic.
- Google Crawler Verification Published crawler ranges and verification procedures illustrate why a user-agent string alone is not sufficient proof of identity.
Sydney Business Web Evidence
- AI Observatory — Verified AI Retrieval Monitoring Overview of Sydney Business Web's production crawler-retrieval measurement system.
- Verified AI Retrieval Evidence Live public evidence showing qualifying search and AI crawler retrieval activity and measured outcomes.
- AI Crawler Monitoring at the Cloudflare Edge Technical background to crawler observation, corroboration and retrieval monitoring.
- A Website — Production AI Observatory Evidence Rolling retrieval measurements recorded during the hosting investigation, including approximately 46%, 66.7%, 77.2%, 85%, 86.4% and 93.3% observed retrieval success states.
- Raw Shared-Hosting Access Logs Production server records used to correlate GPTBot and OAI-SearchBot requests with HTTP 200, 301 and 403 outcomes, exact UTC timestamps and response sizes.
- Wordfence and Application-Level Checks Investigation included Wordfence event files, hit records, blocked-IP records, active block records and account-visible PHP and WordPress error logs.
Evidence boundary — 20 September 2026: the production evidence establishes intermittent 403 responses affecting verified OpenAI crawler traffic and supports investigation of an upstream hosting-security decision. A ModSecurity adjustment was relevant during the earlier remediation of A Website, but at the time of publication the specific provider-side mechanism responsible for the later OpenAI 403 events had not yet been conclusively identified. The hosting provider was supplied with exact timestamps, source addresses, requested paths, response codes and response sizes for investigation.